What is Robots.txt?

Published on November 10, 2026 • Last updated November 10, 2026

Official Definition

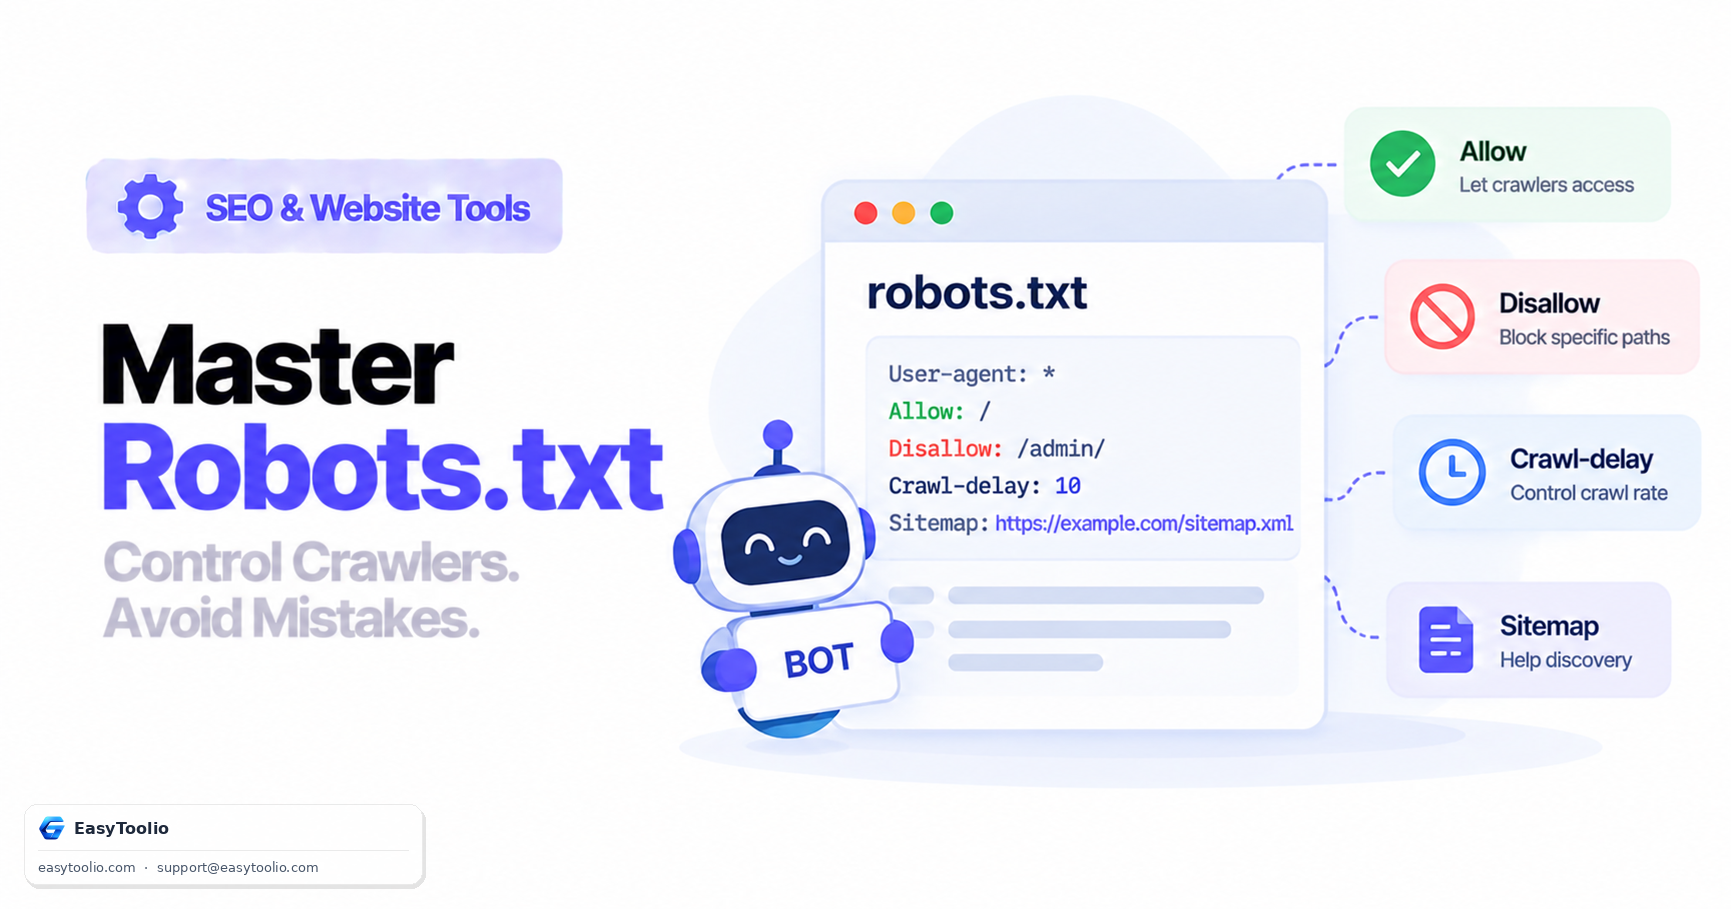
A robots.txt file is a plain text file placed at the root of a website that uses the Robots Exclusion Standard to instruct automated search engine crawlers which URLs they may or may not access.

Detailed Explanation

In-Depth Guide

Key Takeaway

Web crawlers and search engine spiders automatically request /robots.txt before crawling any other URL on a website.

By specifying user-agent directives alongside Disallow and Allow rules, website owners prevent crawlers from indexing private admin portals, staging directories, internal search results, or shopping carts.

While robots.txt manages crawler access, it is not an access control mechanism: the file is public, and malicious scrapers can ignore the rules.

Frequently Asked Questions

Not reliably. If external links point to a disallowed URL, Google can still index the URL title without fetching page contents. Use <meta name="robots" content="noindex"> to completely remove a page from search results.

Robots.txt must always reside in the top-level root directory (e.g., https://example.com/robots.txt). Files placed in subdirectories are completely ignored.

Yes. Directory paths and file names in robots.txt rules are strictly case-sensitive (/Admin/ is treated differently than /admin/).

What do you need to work out next?

Search 276+ free tools by name, or pick a category below. Every one runs instantly in your browser — no signup, nothing to install.

More Finance tools
AI ADVISOR & COACH

Ask AI Advisor

Ask AI