An e-commerce site exposes /orders/10482 in a URL, and within a day a competitor has scraped enough sequential order numbers to estimate exactly how many sales the business made last month. That's the auto-increment ID's most cited weakness — but the "just use a UUID" fix that usually follows has its own real costs that only show up once the table has tens of millions of rows.
Choosing a primary key strategy is one of those decisions that looks trivial at the start of a project and becomes expensive to reverse once the table is in production with foreign keys pointing at it everywhere. The right choice depends less on personal preference and more on how distributed your system is and whether IDs are ever generated outside a single database.
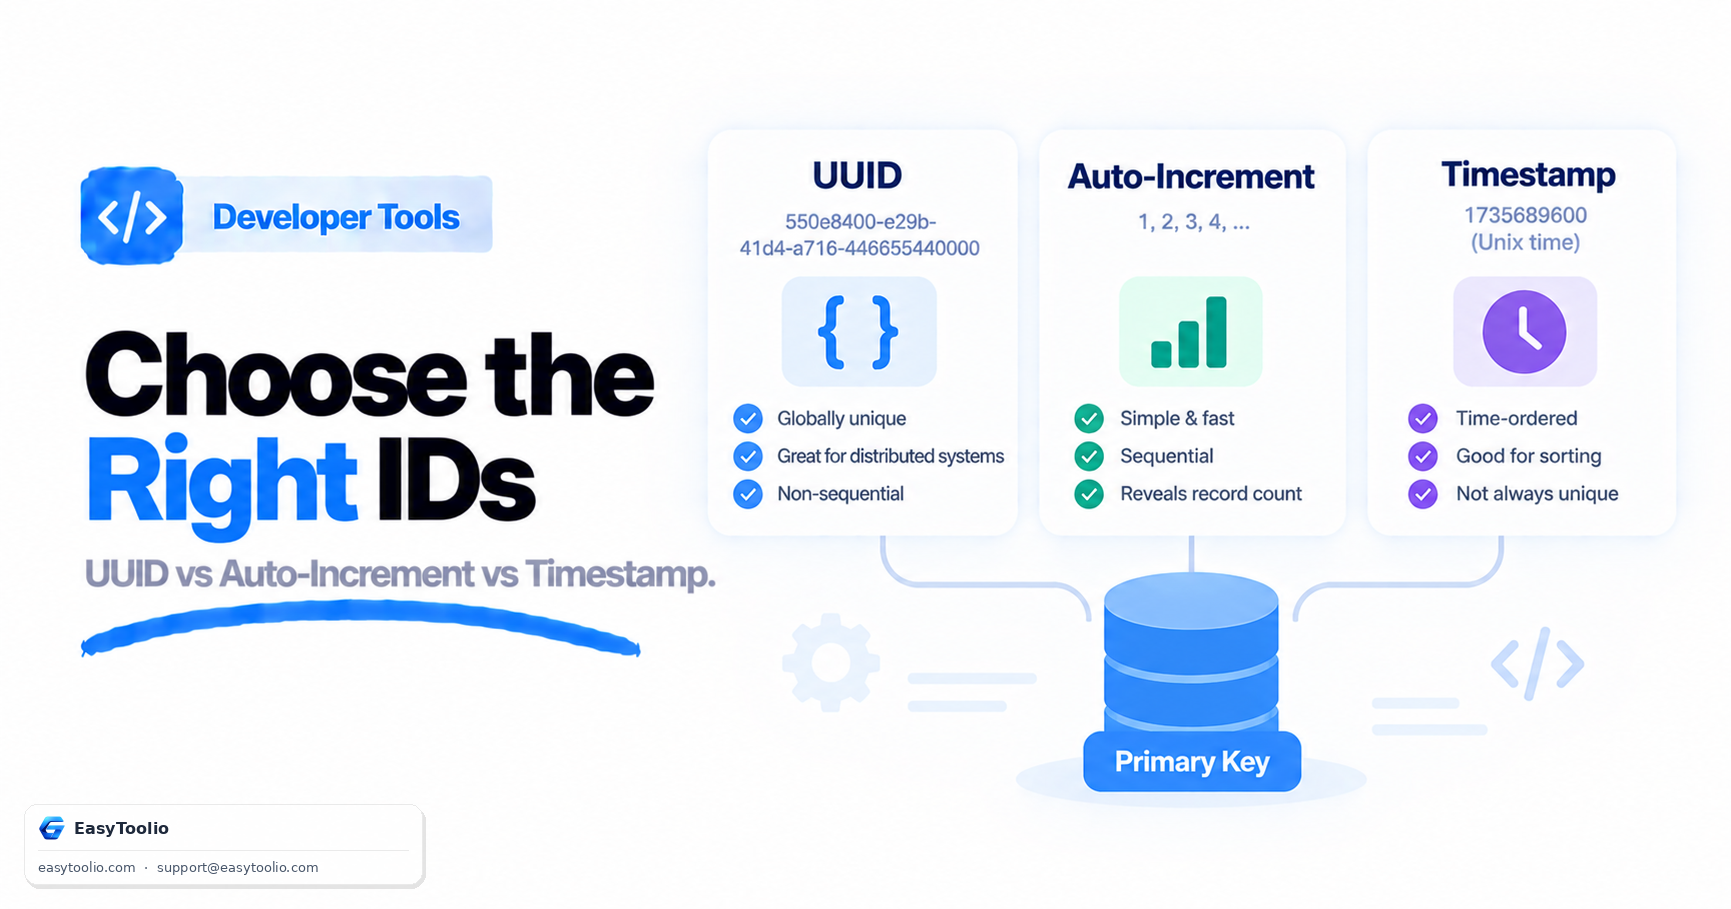
Direct Answer: Auto-increment integers are compact, fast to index, and naturally sortable by creation order, but they reveal record counts to anyone who can see one ID (a competitor can estimate total orders from a single order number) and they create write contention in distributed/multi-writer systems since only one source can safely hand out the "next" number. Random UUIDs (v4) are globally unique with no central coordinator needed, which makes them ideal for distributed systems and offline-generated records, but their randomness means new rows insert at random points across a B-tree index rather than appending at the end, hurting index locality and increasing page splits at scale. UUIDv7 addresses this directly by embedding a timestamp in the leading bits, making UUIDs sortable by creation time while keeping the no-coordination benefit — increasingly the recommended default for new distributed-system schemas.
1. Auto-Increment: Simple, But It Leaks Information and Creates Contention
An auto-increment (or SERIAL/IDENTITY) column is the traditional default: the database itself hands out the next integer, guaranteeing uniqueness within that table with essentially zero configuration.
CREATE TABLE orders (
    id SERIAL PRIMARY KEY,
    customer_id INT NOT NULL,
    total DECIMAL(10,2)
);
-- id: 1, 2, 3, 4... assigned in strict insertion order
The problems are structural, not incidental. Information leakage: exposing id=10482 in a public URL tells anyone paying attention roughly how many orders exist. Write contention: because only the database instance holding the sequence can hand out the next value safely, this becomes a bottleneck the moment you need multiple writers (e.g., sharded databases, multi-region writes, or offline-generated records that need to merge later) — there's no way for two independent nodes to generate non-colliding sequential integers without coordinating.
2. UUID: No Coordination Needed, But Costs Index Locality
A UUID (v4, the common random variant) is a 128-bit value, generated independently by any client or server with no central authority, and collision probability is low enough to treat as effectively zero in practice.
UUIDv4 example: 3f29b6a1-8e47-4c92-9f3d-7a1b6e0d4c88
                (essentially random bits throughout)
You can generate valid, collision-safe UUIDs offline, client-side, before a record ever touches a database — genuinely useful for distributed systems, offline-first mobile apps, and merging data from multiple independently-writing sources. Try generating a batch with a UUID generator to see the format directly.
The tradeoff: because v4 UUIDs are random across their full 128 bits, each new row inserts at an essentially random position in a B-tree primary key index, rather than appending at the rightmost edge the way sequential integers do. At small scale this is invisible; at tens of millions of rows it causes measurably more index page splits, worse cache locality, and larger index size (16 bytes vs. 4-8 for an integer) — real, measurable overhead at scale, not a theoretical concern.
3. UUIDv7: Sortable and Coordination-Free
UUIDv7 (standardized alongside UUIDv6/v8 in RFC 9562) solves the index-locality problem directly by structuring the UUID so its leading bits encode a millisecond-precision Unix timestamp, with the remaining bits still random.
UUIDv7 structure (simplified):
[48 bits: Unix ms timestamp][4 bits: version][12 bits: random]
[2 bits: variant][62 bits: random]

Result: UUIDs generated later always sort after UUIDs generated earlier
This gives you the best of both worlds for most distributed use cases: no central coordinator is needed to generate one, but because the timestamp occupies the leading bits, new UUIDs still insert at the "end" of an index in roughly chronological order, largely restoring the locality benefit that made auto-increment attractive in the first place.
4. Timestamp-Based IDs: Sortable, But Watch Collision Risk
Using a raw timestamp as an ID (e.g., Unix epoch milliseconds) is naturally sortable and human-inspectable, but a bare timestamp alone has an obvious flaw: two records created in the same millisecond on the same node collide outright. Real timestamp-based ID schemes (like Twitter's Snowflake) combine a timestamp with a machine/worker ID and a per-millisecond sequence counter specifically to avoid this. Checking how a raw Unix timestamp actually decodes is easy with a Unix timestamp converter when debugging ID-related sort-order issues.
5. Decision Framework
| Scenario | Recommended strategy | Why |
|---|---|---|
| Single-database app, internal-only IDs | Auto-increment | Simplest, most compact, best index locality |
| IDs ever exposed in public URLs | Auto-increment + separate public slug/UUID, or UUIDv7 | Avoid leaking sequential counts directly |
| Multi-region or sharded writes | UUIDv7 (or v4 if sort order doesn't matter) | No central coordinator needed |
| Offline-first / client-generated records | UUIDv4 or v7 | Must be generable without a live DB connection |
| High-volume time-series data | Snowflake-style ID or UUIDv7 | Sortable, collision-safe, coordination-free |
Frequently Asked Questions
Is UUIDv4 slower than auto-increment for inserts?
At small table sizes the difference is negligible; at large scale (tens of millions of rows) random UUIDv4 inserts do measurably degrade due to worse B-tree locality — UUIDv7 largely closes this gap by keeping new values roughly ordered.
Can I just hash an auto-increment ID to hide it in URLs?
That's a common pattern (or using a separate public slug column), but note a simple reversible hash or short obfuscation isn't a security boundary — if hiding the count matters, use a properly random identifier, not just an encoded version of the sequential one.
Are UUIDs guaranteed unique?
Practically, yes — UUIDv4 has 122 random bits, making collision probability astronomically low, though not mathematically zero. For most engineering purposes this is treated as a non-issue.
What database storage size difference does UUID vs integer actually make?
A UUID is 16 bytes (36 characters as a string); a standard integer auto-increment is typically 4 or 8 bytes. Across a large table with many foreign-key references to that ID, this difference compounds significantly in both storage and index size.
Should I switch an existing auto-increment table to UUIDs?
Usually only if you're actually adding multi-writer/distributed requirements — migrating primary keys on an existing table with foreign key references is a significant, error-prone undertaking, so it's worth confirming the distributed use case is real before committing to it.
References: RFC 9562 (UUID, including UUIDv7), RFC 4122 (original UUID specification).