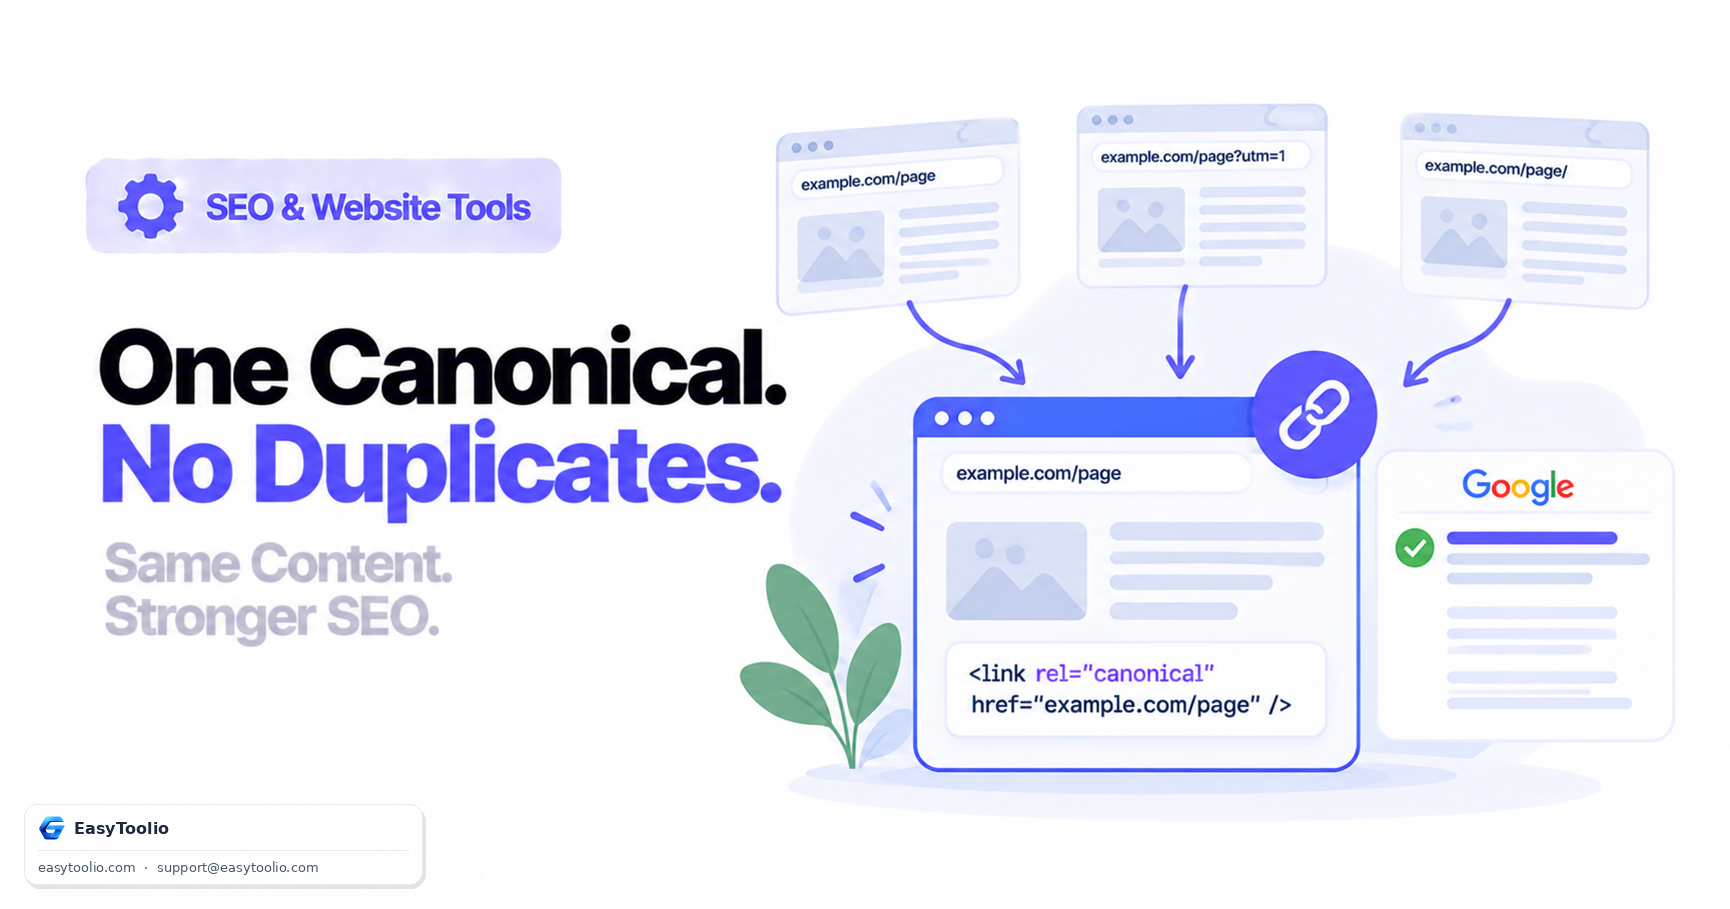
Most sites generate far more URLs than they have unique pieces of content. Sort parameters, tracking codes, session identifiers, print-friendly versions, and HTTP/HTTPS or www/non-www variants can all serve the same content under different URLs. The canonical tag exists specifically to resolve that ambiguity for search engines.
Direct answer: A canonical tag — <link rel="canonical" href="https://example.com/page"> placed in the page <head> — tells search engines which URL is the single authoritative version of a piece of content when multiple URLs could serve it. Google doesn't apply a formal "duplicate content penalty," but unresolved duplicates split ranking signals across multiple URLs instead of consolidating them onto one, and waste crawl budget re-crawling near-identical pages. A canonical tag is a strong hint, not a directive — search engines generally respect it, but they can override it if other signals (internal links, sitemap entries, redirects) point clearly to a different URL.
What Problem Canonical Tags Solve
Consider a product page reachable through several URLs: example.com/shoes, example.com/shoes?color=red, example.com/shoes?utm_source=newsletter, and example.com/shoes/. To a user, these are all "the shoes page." To a crawler without guidance, they can look like four separate pages with substantially overlapping content — each one potentially competing with the others in search results instead of combining their signals onto the one URL that matters.
Canonical Tag Syntax
<!-- Placed in the <head> of https://example.com/shoes?color=red -->
<link rel="canonical" href="https://example.com/shoes" />
This tells search engines: even though this parameterized URL was crawled, attribute ranking signals to the clean master URL instead. The canonical URL should always be absolute (including protocol and domain), not a relative path — relative canonical values are a common implementation bug that can cause the tag to resolve incorrectly depending on how it's parsed.
Canonical Tags vs 301 Redirects
These solve related but different problems, and picking the wrong one is a common mistake:
| Scenario | Canonical tag | 301 redirect |
|---|---|---|
| User experience | User stays on the URL they requested; the page loads normally | User is automatically sent to the destination URL |
| Best suited for | Parameter variants, faceted/filtered views, syndicated content that should stay live at its own URL | Permanently moved pages, domain migrations, merged content that shouldn't exist at the old URL anymore |
| Search engine treatment | A strong hint — search engines usually honor it but weigh other signals too | A definitive instruction — the index is updated to the new URL |
| Reversibility | Easy to remove or change | Sending users through a redirect chain has real UX and performance cost |
If the old URL genuinely shouldn't exist anymore, redirect it. If it needs to stay live and functional (a filtered product view, for example) but shouldn't compete with the canonical version in search, use a canonical tag instead.
Best Practices
- Use absolute URLs.
https://example.com/page, not/page— relative canonical values are prone to misresolution across templating systems. - Self-reference every unique page. Every standalone, canonical-worthy page should point its canonical tag at its own clean URL — this is a defensive best practice even for pages with no obvious duplicates, since it removes ambiguity if a duplicate appears later.
- Keep canonical URLs consistent with your sitemap. If your sitemap lists a URL that differs from what that page's own canonical tag declares, you're sending a mixed signal about which version is authoritative.
- Never chain canonicals. Page A's canonical should point directly to the true final version, not to Page B, whose canonical then points to Page C. Chains add uncertainty about which URL is actually meant to win.
- Don't canonicalize across genuinely different content. A canonical tag should point to a near-duplicate or parameterized variant of the same content — pointing it at an unrelated page is a misuse that search engines will typically disregard.
What Happens When a Canonical Tag Breaks
If a canonical tag points to a URL that returns a 404, a redirect, or is blocked by robots.txt, search engines generally disregard that broken signal and fall back to determining the canonical URL algorithmically using other available signals — internal linking patterns, sitemap entries, and duplicate-content clustering. That fallback doesn't always pick the version you'd have chosen, which is why keeping canonical targets valid and reachable matters.
Canonical Tags and Cross-Domain Syndication
Canonical tags aren't limited to consolidating duplicates on your own domain — they also work across domains. If you syndicate an article to a partner site and want the ranking credit to stay with your original, the syndicated copy's canonical tag can point back to your original URL, provided the partner is willing to add it. This is the standard, cooperative way to handle content syndication without creating duplicate-content competition between the original and the syndicated copy. It only works if the receiving site actually implements the tag — a syndication partner that strips or ignores it defeats the purpose.
Common Implementation Pitfalls
- CMS defaults that self-canonicalize incorrectly. Some platforms auto-generate canonical tags based on the raw request URL, including tracking parameters, instead of the clean intended URL — worth verifying rather than assuming the default is correct.
- Canonical tags in the
<body>instead of<head>. Per the specification, canonical tags are only recognized when placed in the document<head>; a tag rendered in the body is typically ignored. - Protocol or www mismatches. A canonical pointing to
http://when the site serveshttps://, or omittingwwwwhen the rest of the site uses it, creates the same inconsistency problem the tag was meant to resolve.
Frequently Asked Questions
What happens if a canonical tag points to a 404 page? Search engines treat the broken canonical as unreliable and fall back to selecting a canonical URL on their own, based on other signals like internal links and sitemap data — the outcome may not match your intended URL.
Can a page have more than one canonical tag? No — if multiple conflicting canonical tags exist on a page (which can happen accidentally through CMS plugins or template bugs), search engines will generally ignore all of them and choose independently, since the signal is contradictory.
Should paginated pages canonicalize to page 1? Generally no — each page in a paginated series usually represents genuinely different content and should self-canonicalize, unless there's a "view all" version that legitimately supersedes the paginated set.
Does a canonical tag stop a page from being crawled?
No. Unlike robots.txt or a noindex tag, a canonical tag doesn't block crawling — the page is still crawled normally; the tag only affects which URL gets credit for the content in the index.
Is rel="canonical" the same as hreflang?
No. Canonical tags consolidate duplicate content onto one URL; hreflang tags indicate language/region alternatives of the same content that should all remain indexed separately for their respective audiences. They serve different purposes and shouldn't be confused.
Audit your canonical tag implementation with our meta tag analyzer, confirm canonical URLs match your sitemap entries with the XML sitemap validator, check that canonical targets return a clean 200 status with the HTTP status checker, and clean up parameterized URLs with the URL encoder/decoder.